
Let the LLM build the engine, not run it
Type a question about your Book. The report is there before you finish reading it.
That’s Report, a Bkper app I built in five days, recorded at real speed on our public template Book. One input, no submit button, any of the 133 languages Bkper speaks.
Ask Bkper Agent to build the same report and it gets it right too. It just takes about two minutes.
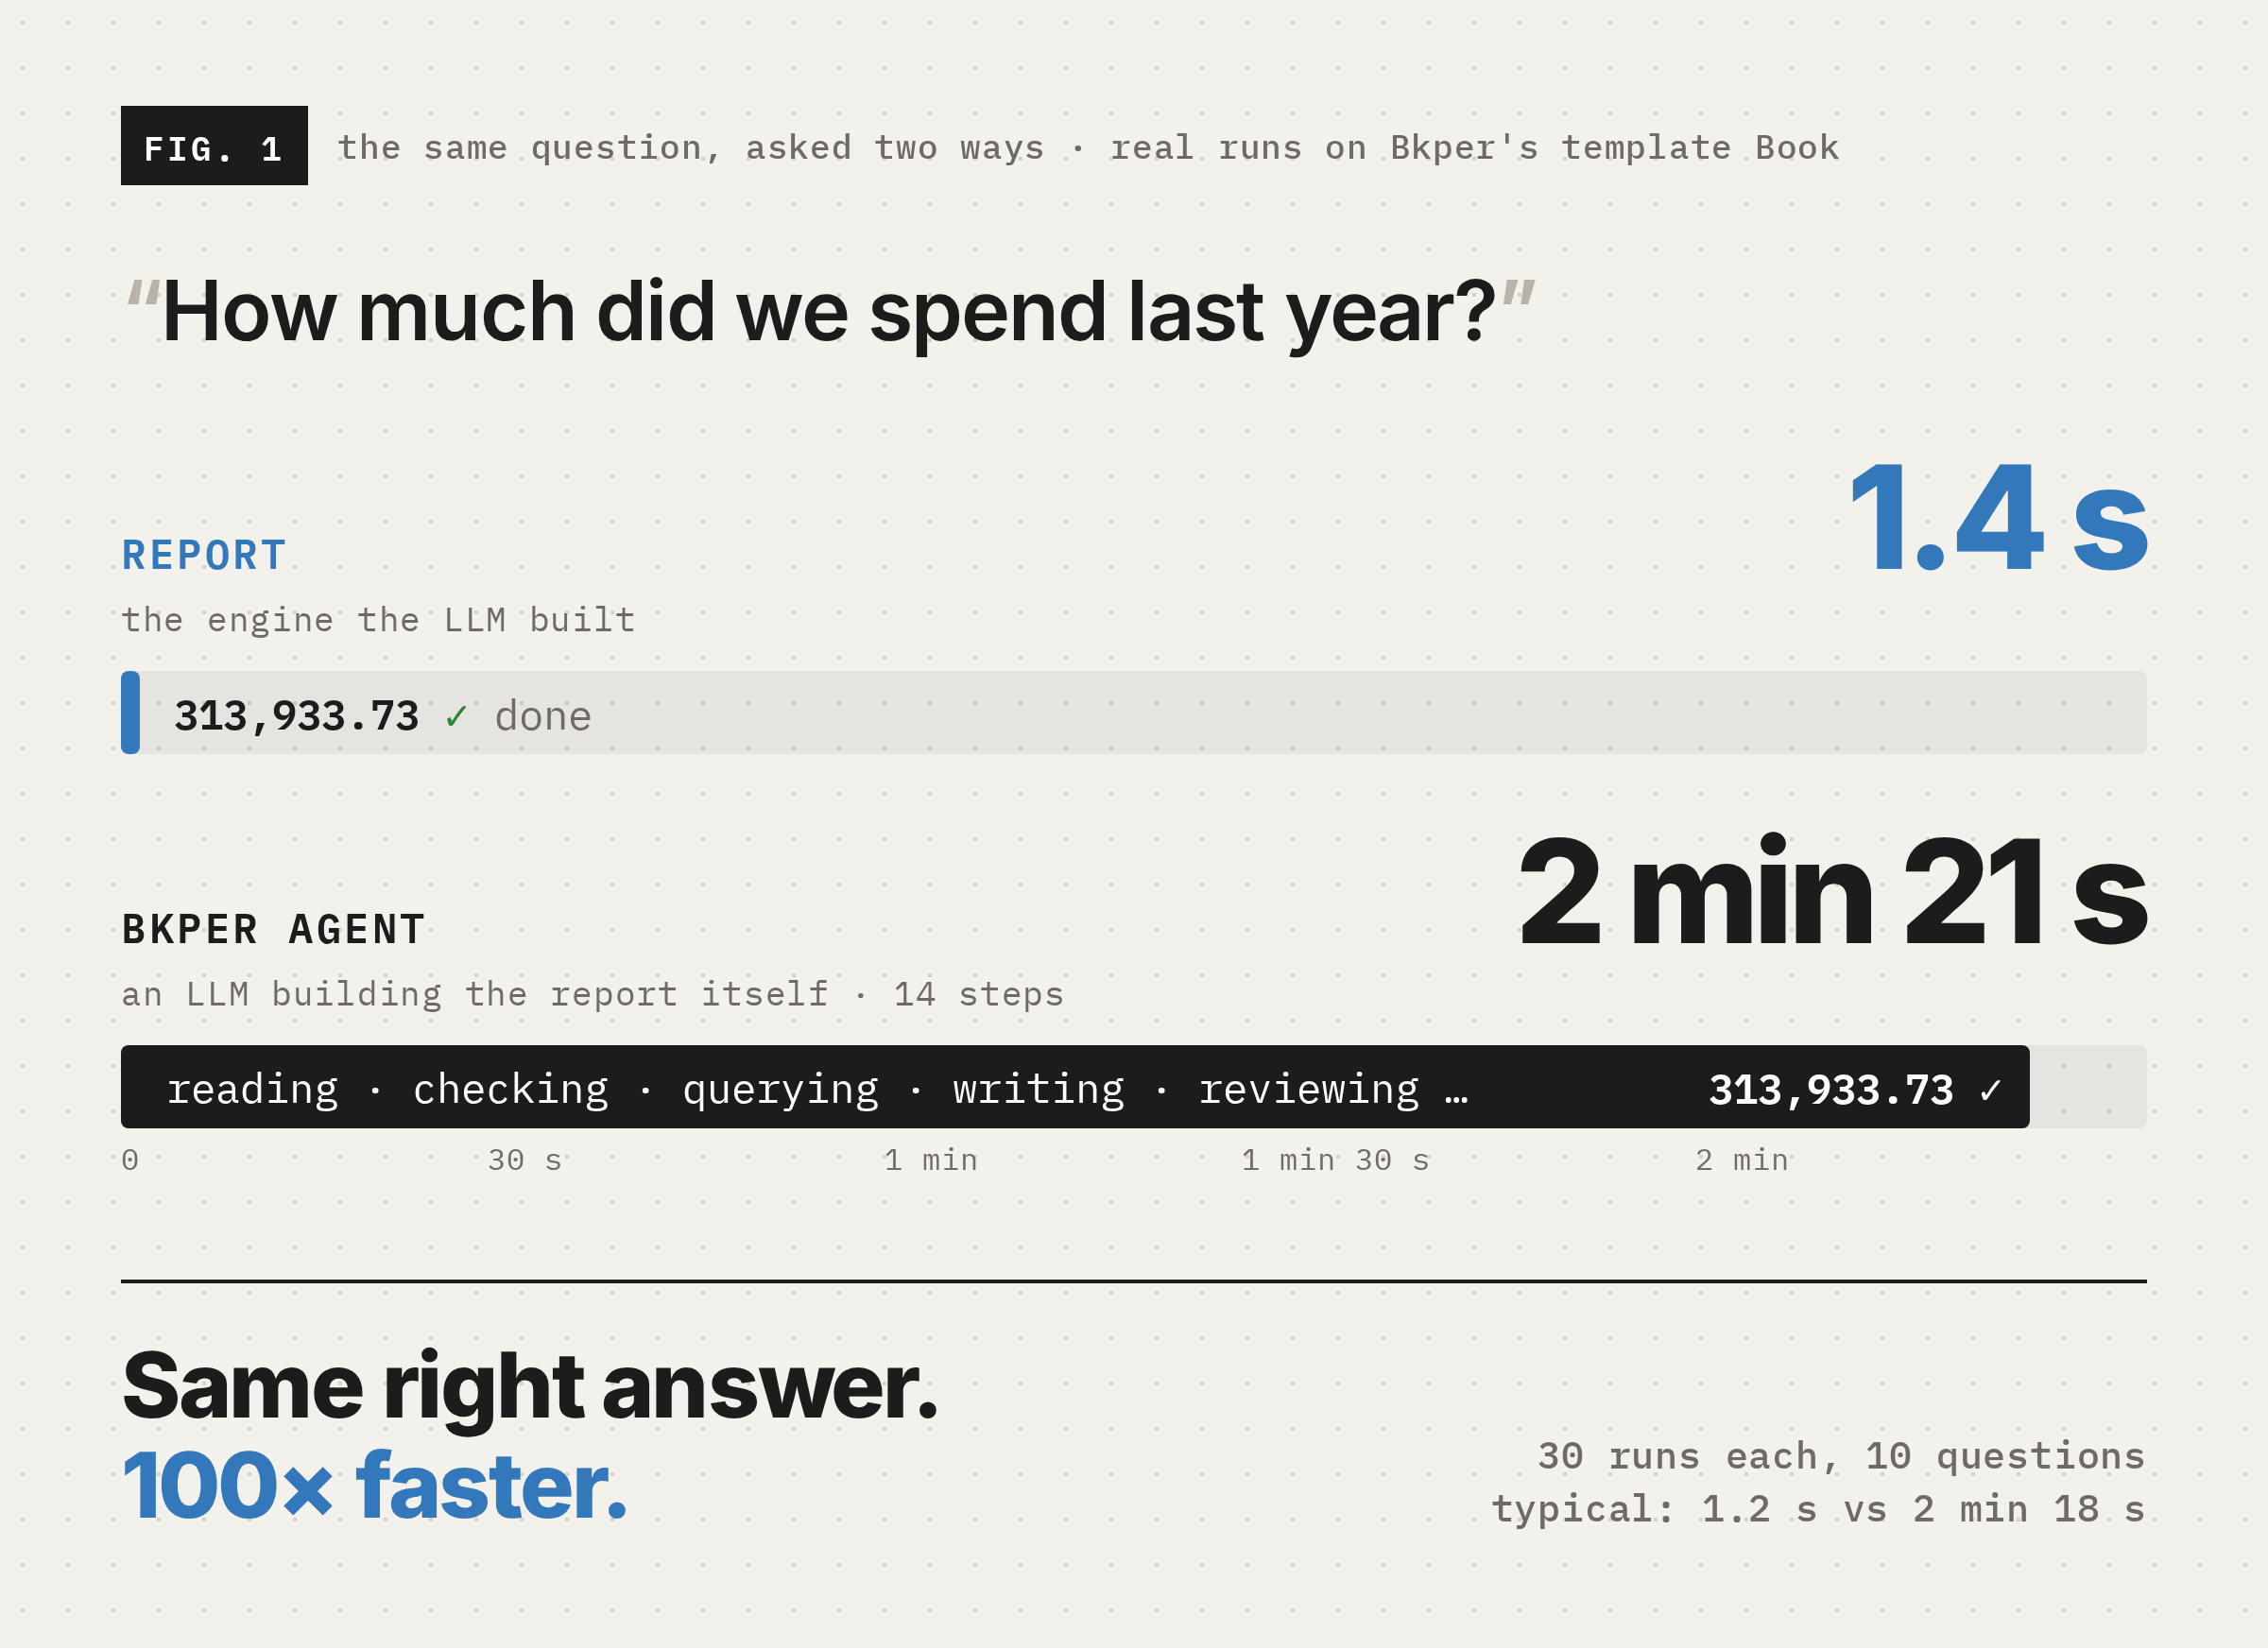
In the time the Agent builds one report, you can ask Report a hundred questions.
Right is not enough
We asked ten real questions, three times each. The Agent got all thirty right, in about two minutes and a quarter of a million tokens each. And on four of the ten, it took a different road on different runs: Q1 revenue read from Revenue once, from Net Income the next.
Same number today. Different road tomorrow.
An LLM can show the right numbers 99 times and be wrong on the 100th, and you can’t test a path it invents every time. In accounting, you can’t afford to be almost correct.
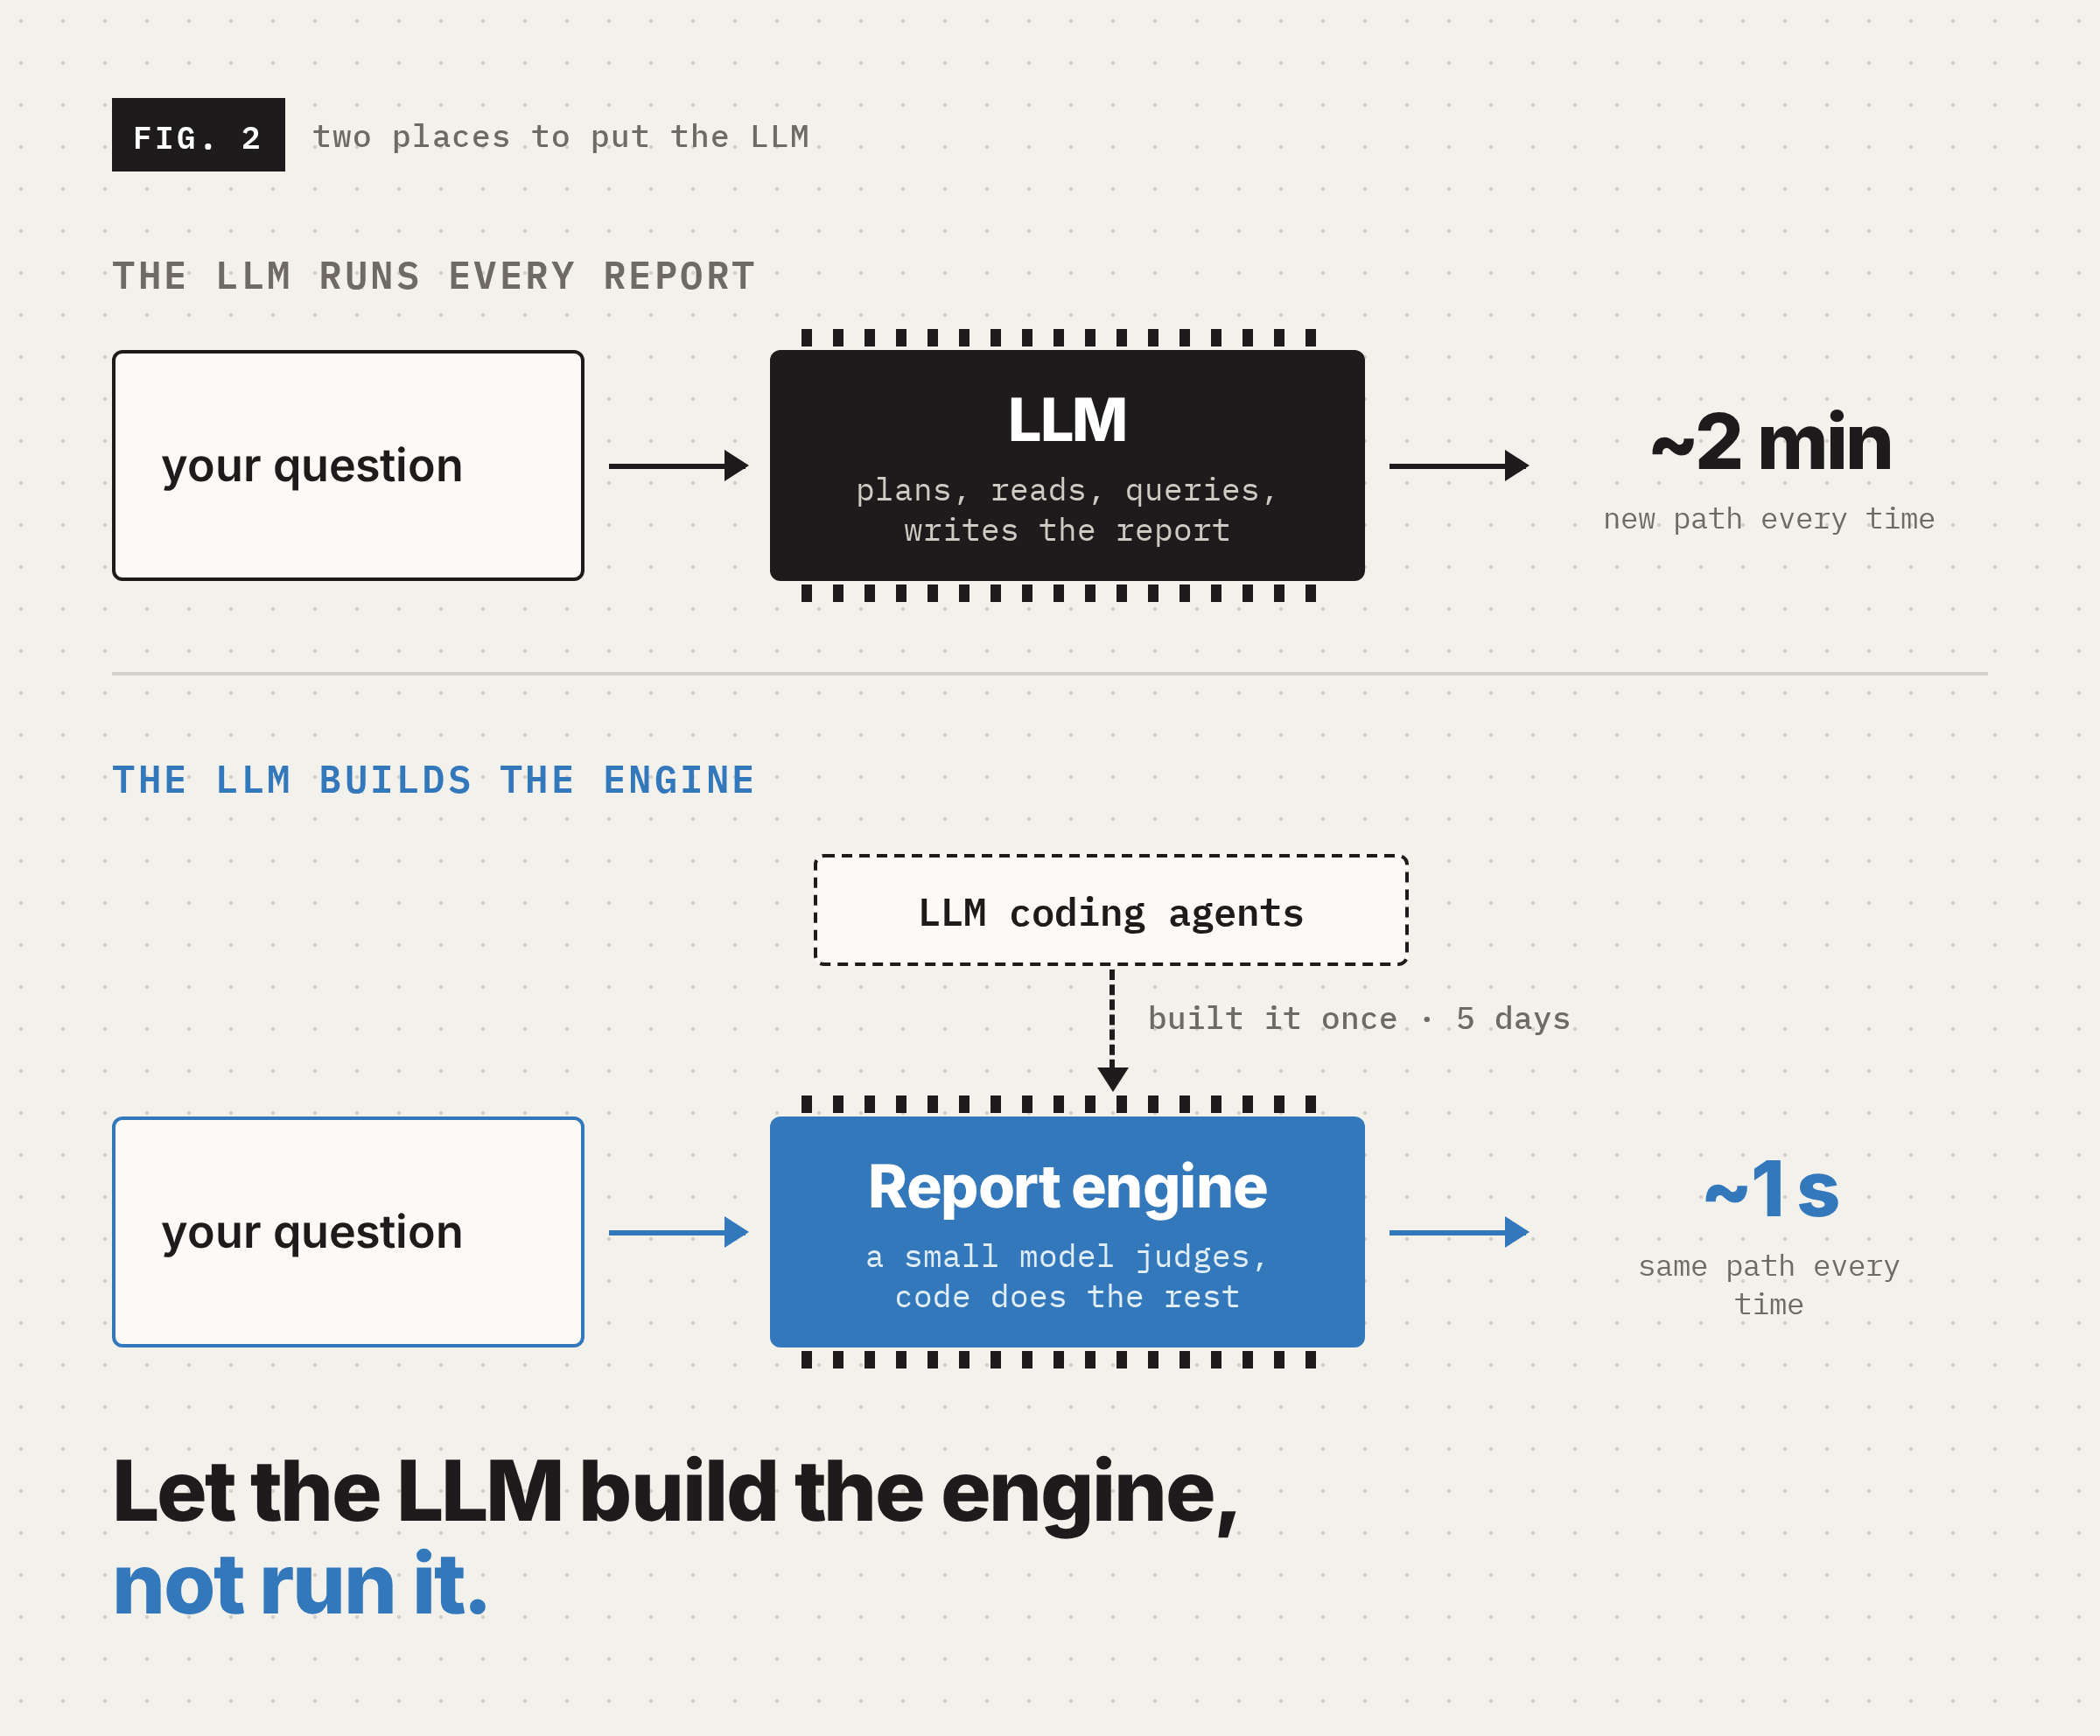
The LLM built the engine
Here’s the twist: LLM coding agents wrote every line of Report. 108 commits in five days, about 20,000 lines of TypeScript, 77 test files. I described what I wanted, argued about the design, and let the agents build, test and verify.
The LLM is all over Report. It’s in the build, not in the request.
Ask for the parts, not the answer
Each request still asks Jev, a small System One model, what your sentence means. How we ask made all the difference.
At first, Jev picked the period from a list of 255 options. Asked for revenue last year compared to 2023, it answered 2025 vs 2024. It got 73% of our 561 period tests right.
So we asked for the parts instead: how long, which year, compared with what. Questions a bookkeeper answers at a glance. Code puts the answers into a query, and Bkper does the math. Same tests: 100%.
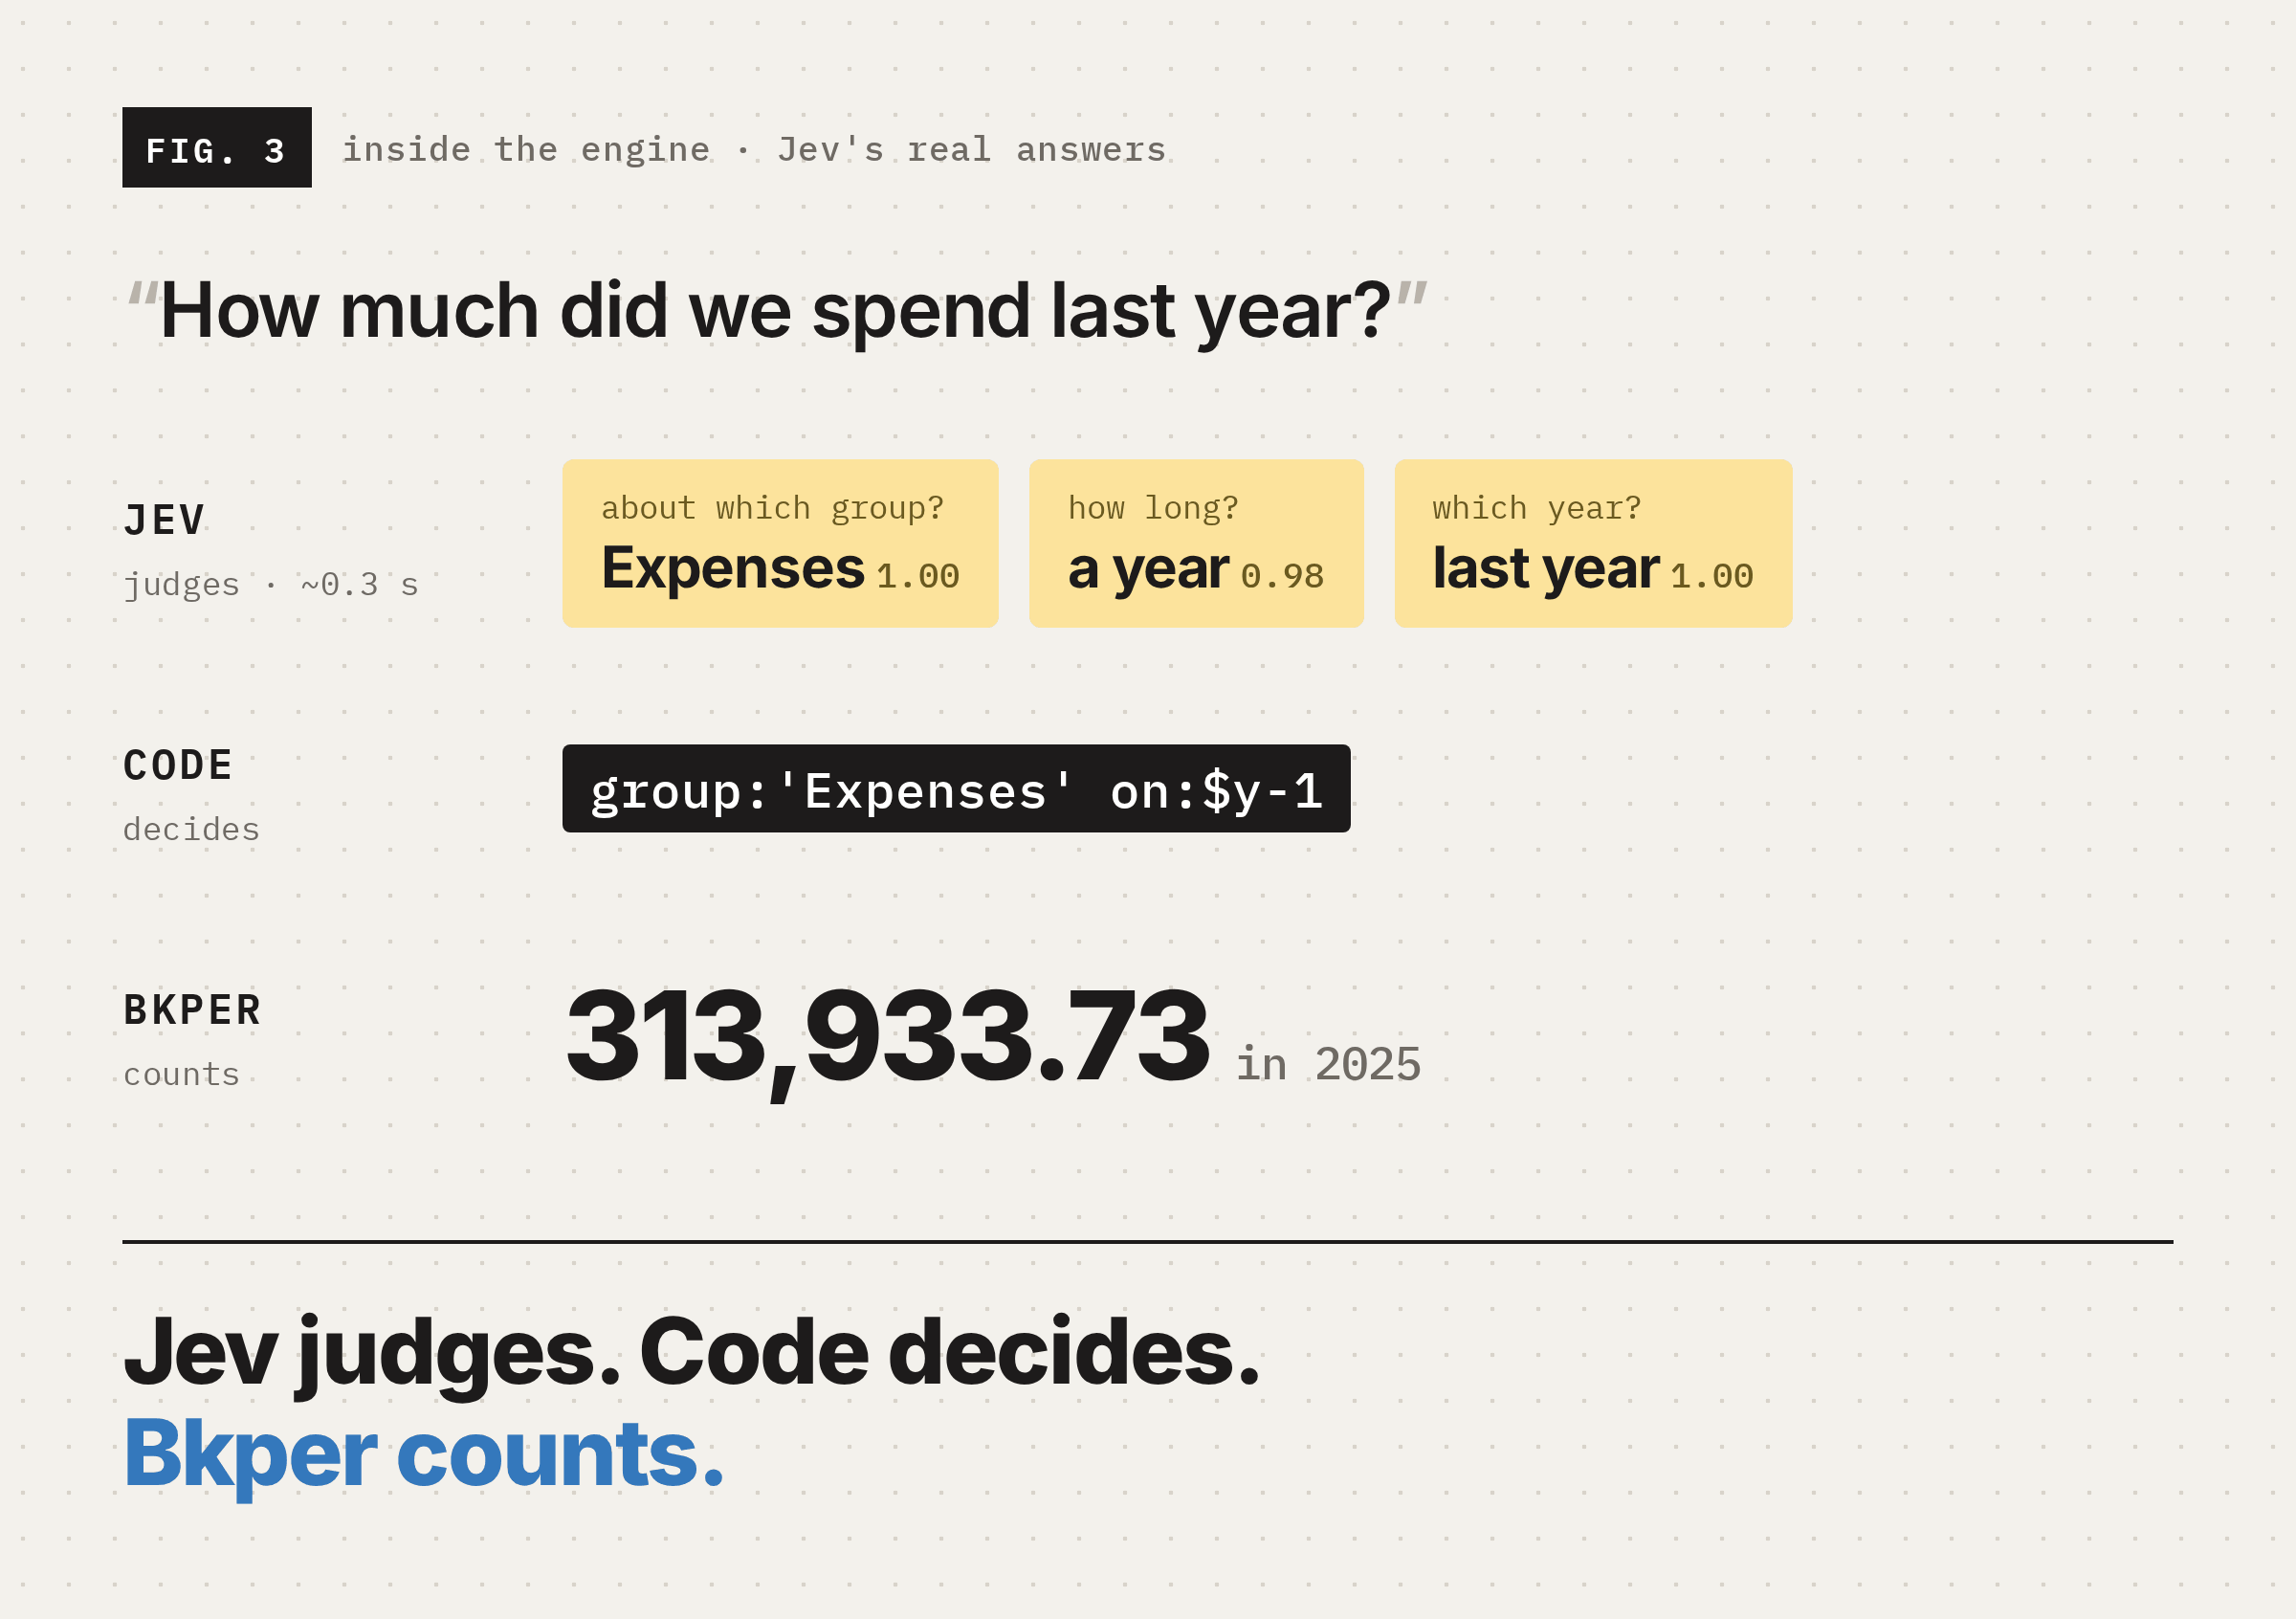
As Allie Laabs puts it in Don’t Call It a Decision Model: Jev makes judgments, code makes decisions.
A miss you can fix
Report isn’t perfect. Our benchmark caught it reading How much did we spend last year? as Net Income, not Expenses. Every run, the same way, with the query right on the screen.
Because the meaning is split into parts, we could see which one was wrong: which group? We pinned it with a test, changed that one question, and it passed. Fixed for every Book, in every language.
An LLM’s 100th report fails somewhere new each time. An engine’s miss is a bug with an address.
The Agent didn’t lose its job
In a Book with Report installed, ask Bkper Agent for a report and it asks Report, then shows you the same interactive report. When Report can’t help, like a messy chart of accounts or a custom pack for your accountant, it hands you to the Agent with the request already written.
If you’re building an app
- Use the LLM to build. Code, tests, evaluations, translations.
- Keep it out of the request when the answer must be exact.
- Ask the model for judgments only. Let code hold the facts, the rules and the math.
- Turn every miss into a test before you fix it.
Report is open source, and System One models are available to every Bkper app. Building something similar? Find me on X at @maelcaldas.